Given manifold-valued data \(X_1,X_2,\ldots,X_N \in \mathcal{M}\), this algorithm draws a weighted coreset using the lightweight importance-sampling scheme proposed by the reference below. The Euclidean approximation theorem is not asserted for arbitrary manifold geometries.
Arguments
- riemobj
a S3
"riemdata"class for \(N\) manifold-valued data.- M
positive integer number of independent draws (default: \(\lceil N/2 \rceil\)). Values greater than \(N\) are permitted.
- geometry
(case-insensitive) name or saved specification of a geometry supporting means. Legacy aliases
"intrinsic"and"extrinsic"are accepted; seeriem.geometry.- ...
extra parameters including
- maxiter
maximum number of iterations to be run (default:50).
- eps
tolerance level for stopping criterion (default: 1e-5).
Value
a named list containing
- coreid
a length-\(M\) index vector; repeated indices are retained.
- weight
a length-\(M\) vector of importance weights, \(1/(M q_i)\) for each drawn index \(i\).
Details
Each index is drawn independently with replacement, with probability
\(q_i = 1/(2N) + d(X_i,\mu)^2/(2\sum_j d(X_j,\mu)^2)\), where
\(\mu\) is the computed mean in the selected geometry. When all distances
are zero the probabilities are uniform. Thus, for any fixed centers, the
importance-weighted coreset cost is an unbiased estimate of the full-data
squared-distance cost. This identity does not require the computed mean to
be globally optimal. Duplicate draws count separately and must not be
discarded without summing their weights. Use set.seed() for reproducibility.
Validation status
This retained legacy interface is experimental. Its full numerical and
statistical contract has not been independently verified across supported
inputs. See riem-method-contracts and the installed contract
table for method-specific assumptions, restrictions, and evidence scope.
References
Bachem O, Lucic M, Krause A (2018). “Scalable k -Means Clustering via Lightweight Coresets.” In Proceedings of the 24th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining, 1119–1127. ISBN 978-1-4503-5552-0.
Examples
#-------------------------------------------------------------------
# Example on Sphere : a dataset with three types
#
# * 10 perturbed data points near (1,0,0) on S^2 in R^3
# * 10 perturbed data points near (0,1,0) on S^2 in R^3
# * 10 perturbed data points near (0,0,1) on S^2 in R^3
#-------------------------------------------------------------------
## GENERATE DATA
mydata = list()
for (i in 1:10){
tgt = c(1, stats::rnorm(2, sd=0.1))
mydata[[i]] = tgt/sqrt(sum(tgt^2))
}
for (i in 11:20){
tgt = c(rnorm(1,sd=0.1),1,rnorm(1,sd=0.1))
mydata[[i]] = tgt/sqrt(sum(tgt^2))
}
for (i in 21:30){
tgt = c(stats::rnorm(2, sd=0.1), 1)
mydata[[i]] = tgt/sqrt(sum(tgt^2))
}
myriem = wrap.sphere(mydata)
## MDS FOR VISUALIZATION
embed2 = riem.mds(myriem, ndim=2)$embed
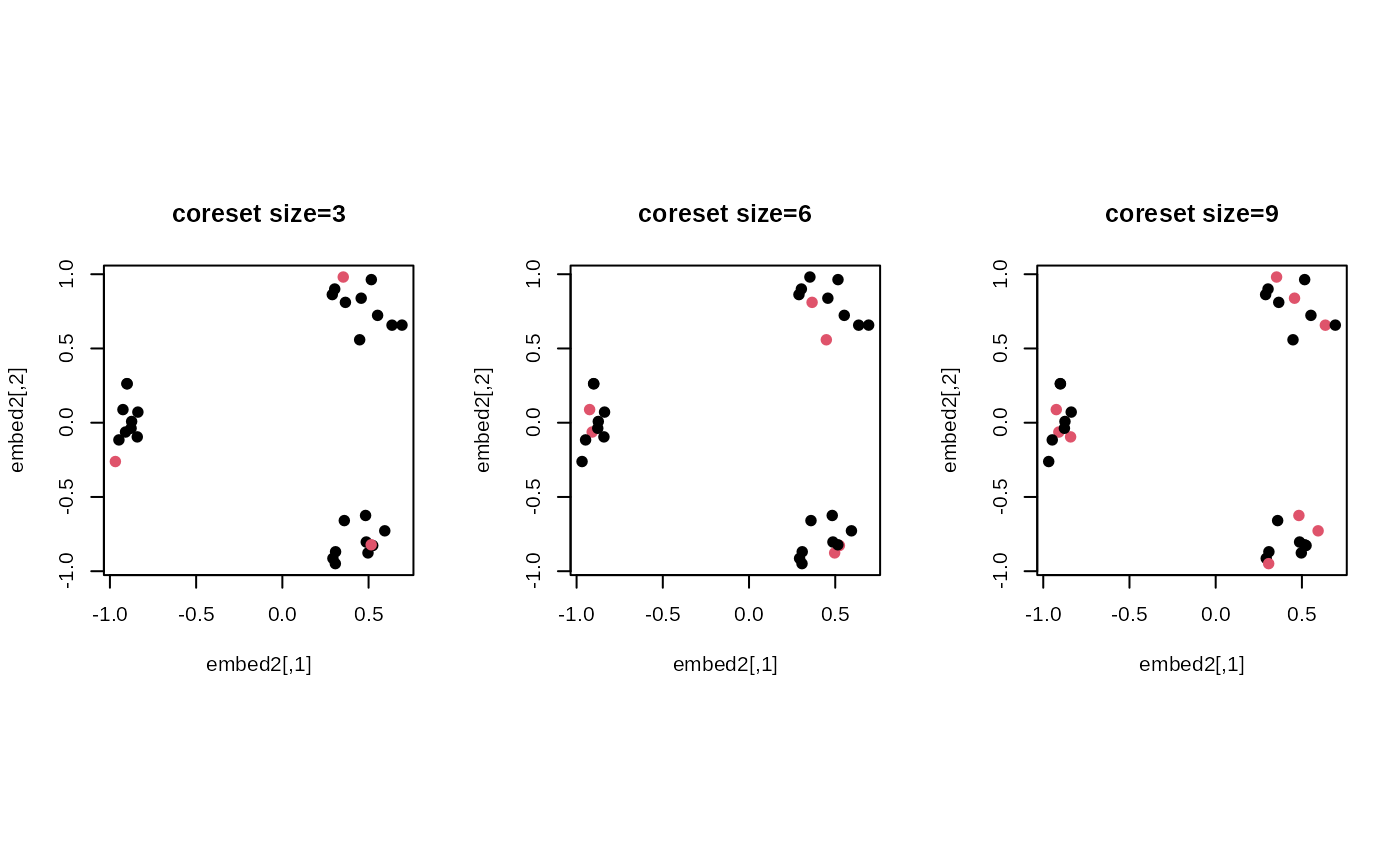
## FIND CORESET OF SIZES 3, 6, 9
core1 = riem.coreset18B(myriem, M=3)
core2 = riem.coreset18B(myriem, M=6)
core3 = riem.coreset18B(myriem, M=9)
col1 = rep(1,30); col1[core1$coreid] = 2
col2 = rep(1,30); col2[core2$coreid] = 2
col3 = rep(1,30); col3[core3$coreid] = 2
## VISUALIZE
opar <- par(no.readonly=TRUE)
par(mfrow=c(1,3), pty="s")
plot(embed2, pch=19, col=col1, main="coreset size=3")
plot(embed2, pch=19, col=col2, main="coreset size=6")
plot(embed2, pch=19, col=col3, main="coreset size=9")
 par(opar)